


Swarm Robotics Practice - Modular Design
-
Swarm Robotics Practice - Modular Design
- Prerequisites
- General Motivation
-
Course Content
-
Getting started
- 1. Download the laboratory package (All operating systems)
-
2. Installation instructions by operating system
- Step 1 — Install Docker Desktop
- Step 2 — Start the laboratory for the first time
- Step 3 — Open the Ubuntu desktop
- Step 4 — Running experiments
- Daily usage after the first execution
- Troubleshooting
- Step 1 — Install Docker
- Step 2 — Enable Docker permissions
- Step 3 — Verify the installation
- Step 4 — Start the laboratory
- Step 5 — Open the Ubuntu desktop
- Step 6 — Running experiments
- Daily usage
- Troubleshooting
- Introduction
- Running the software
- Designing modular control software for robot swarms
- Experimental scenarios
- To be considered
-
Getting started
- Contact
- Credits
Prerequisites
To get the most out of this Swarm Robotics module, it’s helpful to have prior knowdlege on basic mobile robotic systems and to have followed the prior content on Swarm Robotics and the Practical Session on programming collective behaviors.
This session requires you to assemble modular control software, therefore, basic programming skills are recommended. The practical session also requires you to manually tune the parameters of the software, for which basic understanding of optimization processes is useful but not mandatory.
The tools required to develop the excercises are introduced in the material: Docker environments and the ARGoS simulator.
General Motivation
Many of the collective behaviors explored in swarm robotics share common behavioral components. For example, robots may explore the environment by performing random walks, either because they aim to find their peers and aggregate in a single cluster, or because they are looking for regions of interst from which to forage. In this example, a similar building block for a exploration behavior can be used to compose different collective behaviors: aggregation or foraging.
In the previous practical session, these behaviors were programmed manually with the goal of observing whether a given collective behavior would emerge when the robots followed certain rules. In this session, the problem is taken a step further. Instead of programming the robots directly, you are given a number of behavioral components that can be combined and tuned to produce control software for a variety of swarm robotics problems.
This introduces you to the use of optimization-based processes for designing collective behaviors in robot swarms. Given a performance metric that describes a swarm mission, the goal is to find suitable control software for the robots that improves their performance. The challenge is not to observe a desired behavior, but rather to optimize the performance of the swarm.
This enginnering approach to swarm robotics focuses in designing good performing systems, and not much on the specifics of the behavior obtained. After experimenting with this manual optimization-based process, you will be ready to set up your own architectures and implement your own tuning methods (for example, those based on heuristic optimization and reinforcement learning).
Course Content
Getting started
1. Download the laboratory package (All operating systems)
You will need approximately 8 GB of free disk space.
Download the laboratory package from the following link:
https://drive.google.com/file/d/1xqCiMZPd4pzFfCFxcel8zky25Dd0uPOl/view?usp=drive_link
After downloading:
- Extract the compressed file anywhere on your computer.
- Once extracted, you should obtain a folder named:
modular_design_lab/
This folder already contains:
- Docker configuration files
- The swarm robotics experiments
- The AutoMoDe interface
- The ARGoS3 configurations
- All required scripts and dependencies
The structure should look similar to this:
modular_design_lab/
├── docker-compose.yml
└── README.md/
2. Installation instructions by operating system
🪟 Windows
Step 1 — Install Docker Desktop
If you already install docker from previous practice, jump to Step 2.
Docker is the software that will run the complete Ubuntu laboratory environment on your computer.
You can install Docker Desktop in either of these ways:
- From the Microsoft Store (recommended for beginners)
- From the official Docker website:
https://www.docker.com/products/docker-desktop/
During installation, Docker may ask to enable a Windows feature called WSL2 (Windows Subsystem for Linux). This is normal. In most cases, Docker configures it automatically.
After installation:
Restart your computer if Windows requests it. Open the Docker Desktop application. Wait until Docker finishes starting.
You should eventually see a message similar to:
Engine running
inside Docker Desktop.
Step 2 — Start the laboratory for the first time
The first execution must be done from a terminal because Docker needs to download the complete laboratory image.
Open:
- PowerShell, or
- Command Prompt (CMD)
Navigate to the modular_design_lab/ folder.
For example:
cd Desktop\modular_design_lab
Your path may be different depending on where you extracted the files.
Start the container:
docker compose up
The first startup may take several minutes because Docker must download a large image.
Wait until the startup process finishes.
Step 3 — Open the Ubuntu desktop
Open the following URL in your web browser:
http://localhost:6080/vnc.html
Click:
Connect
When prompted for the password, enter:
swarmbot
You should now see the Ubuntu desktop environment running inside your browser.
Step 4 — Running experiments
Verify that you are able to run an experiment by entering the following commands in the command.
Open a terminal inside the Ubuntu desktop and move to the project directory:
cd ~/sigsoft-swarms
Load the ARGoS environment variables:
source argos3-env.sh
Start an experiment:
bash start_experiment.sh 1
Open the following URL in the Ubuntu browser:
http://localhost:8088
You should now see the AutoMoDe interface similar to the image below.

Daily usage after the first execution
After the first installation, you usually do not need to use the terminal to launch Docker again.
Instead:
Open Docker Desktop Locate the container named:
sigsoft-swarms
Click the ▶ Start button
You can then reconnect to the container terminal using:
docker exec -it sigsoft-swarms bash
Troubleshooting
The browser says “connection refused”
The container may still be starting. Wait a few seconds and refresh the page.
The installation script fails
Make sure you are running the command inside the container.
Docker does not start
Restart Docker Desktop and verify that WSL2 is enabled.
🐧 Linux
Step 1 — Install Docker
If you already install docker from previous practice, jump to Step 4.
Open a terminal and install Docker:
sudo apt update
sudo apt install docker.io docker-compose-plugin
Step 2 — Enable Docker permissions
Add your user to the Docker group:
sudo usermod -aG docker $USER
Then restart your session or reboot your computer.
If you skip this step, Docker commands may fail unless executed with sudo.
Step 3 — Verify the installation
Run:
docker --version
and:
docker compose version
Both commands should print version information without errors.
—Verify that you are able to run an experiment by entering the following commands in the command.
Open a terminal inside the Ubuntu desktop and move to the project directory:
cd ~/sigsoft-swarms
Load the ARGoS environment variables:
source argos3-env.sh
Start an experiment:
bash start_experiment.sh 1
Open the following URL in the Ubuntu browser:
http://localhost:8088
You should now see the AutoMoDe interface similar to the image below.
Step 4 — Start the laboratory
Open a terminal inside the modular_design_lab/ directory and run:
docker compose up
The first startup may take several minutes because Docker must download the required images.
Step 5 — Open the Ubuntu desktop
Open the following URL in your browser:
http://localhost:6080/vnc.html
Click:
Connect
Password:
swarmbot
You should now see the Ubuntu desktop environment.
Step 6 — Running experiments
Verify that you are able to run an experiment by entering the following commands in the command.
Open a terminal inside the Ubuntu desktop and move to the project directory:
cd ~/sigsoft-swarms
Load the ARGoS environment variables:
source argos3-env.sh
Start an experiment:
bash start_experiment.sh 1
Open the following URL in the Ubuntu browser:
http://localhost:8088
You should now see the AutoMoDe interface similar to the image below.
Daily usage
Open a terminal inside the modular_design_lab/ directory.
To stop the laboratory:
docker compose stop
To start it again later:
docker compose start
To completely remove the container:
docker compose down
Your files inside the project directory will remain safe.
Troubleshooting
Permission denied errors
The Docker permissions were probably not applied correctly.
Try:
newgrp docker
or restart your session.
The browser page does not open
Check that the container is running:
docker compose ps
🍎 macOS
Introduction
In this practical session, the students will use a modular approach to design control software for a swarm of 20 e-puck robots that must perform a set of missions in the ARGoS3 simulator. The missions require the robots to communicate, navigate the environment, react to events, and display spatial-organization properties. Below the e-puck that is used as a basis for the simulations.
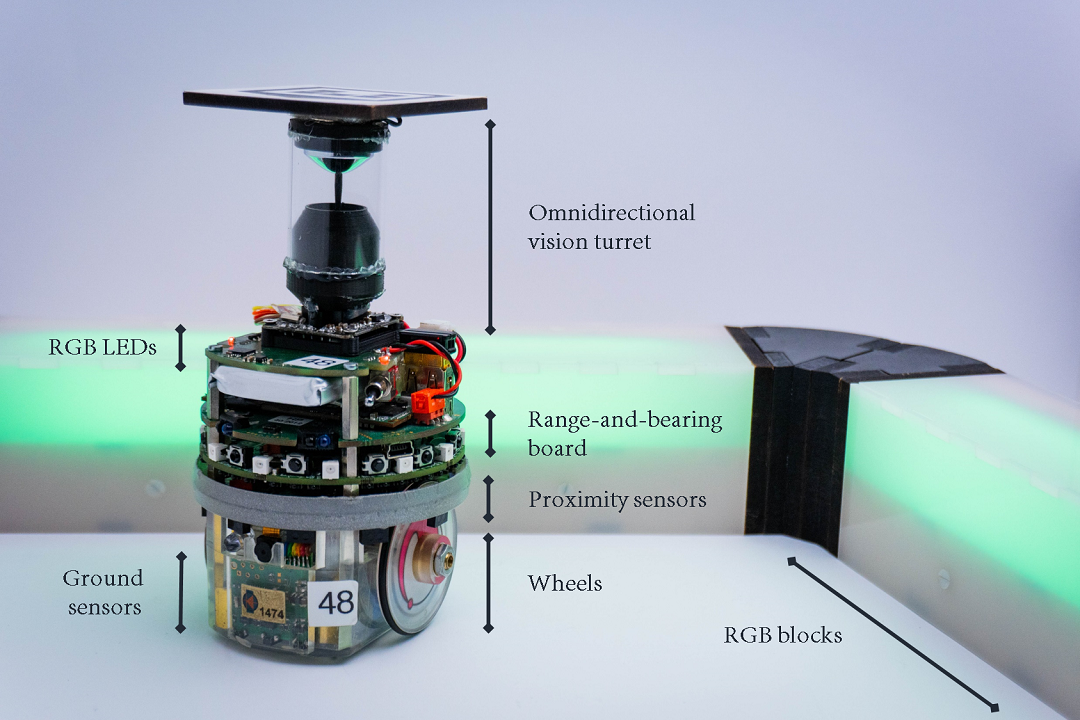 Figure 1. The e-puck considered in the practical session, by Garzón Ramos & Birattari.
Read details
The e-puck operates with the following sensing and actuation capabilities:
- Proximity sensors: 8 sensors distributed around the chassis for obstacle detection.
- Ground sensors: 3 sensors that distinguish between black, gray, and white floor surfaces.
- Range-and-bearing board: estimates the number and aggregate relative position of neighboring robots within 0.5 m.
- Omnidirectional camera: a 360° turret that detects colored lights (red, blue, green, cyan, magenta, and yellow) within 0.5 m and computes an aggregate direction vector for each color.
- Differential wheels: two wheels that can drive the robot at speeds up to 0.12 m/s.
- RGB LEDs: three LEDs on top of the robot that can display cyan, magenta, or yellow.
The walls of the arena in which the e-puck operates can display red, green, and blue.
The exercise is based on TuttiFrutti [3], a modular design method specialized in the realization of collective behaviors for robots that can display and perceive color signals. TuttiFrutti generates control software in the form of probabilistic finite-state machines that combine parametric software modules. Below a simplified example of how a set of behavioral modules are executed in a robot.
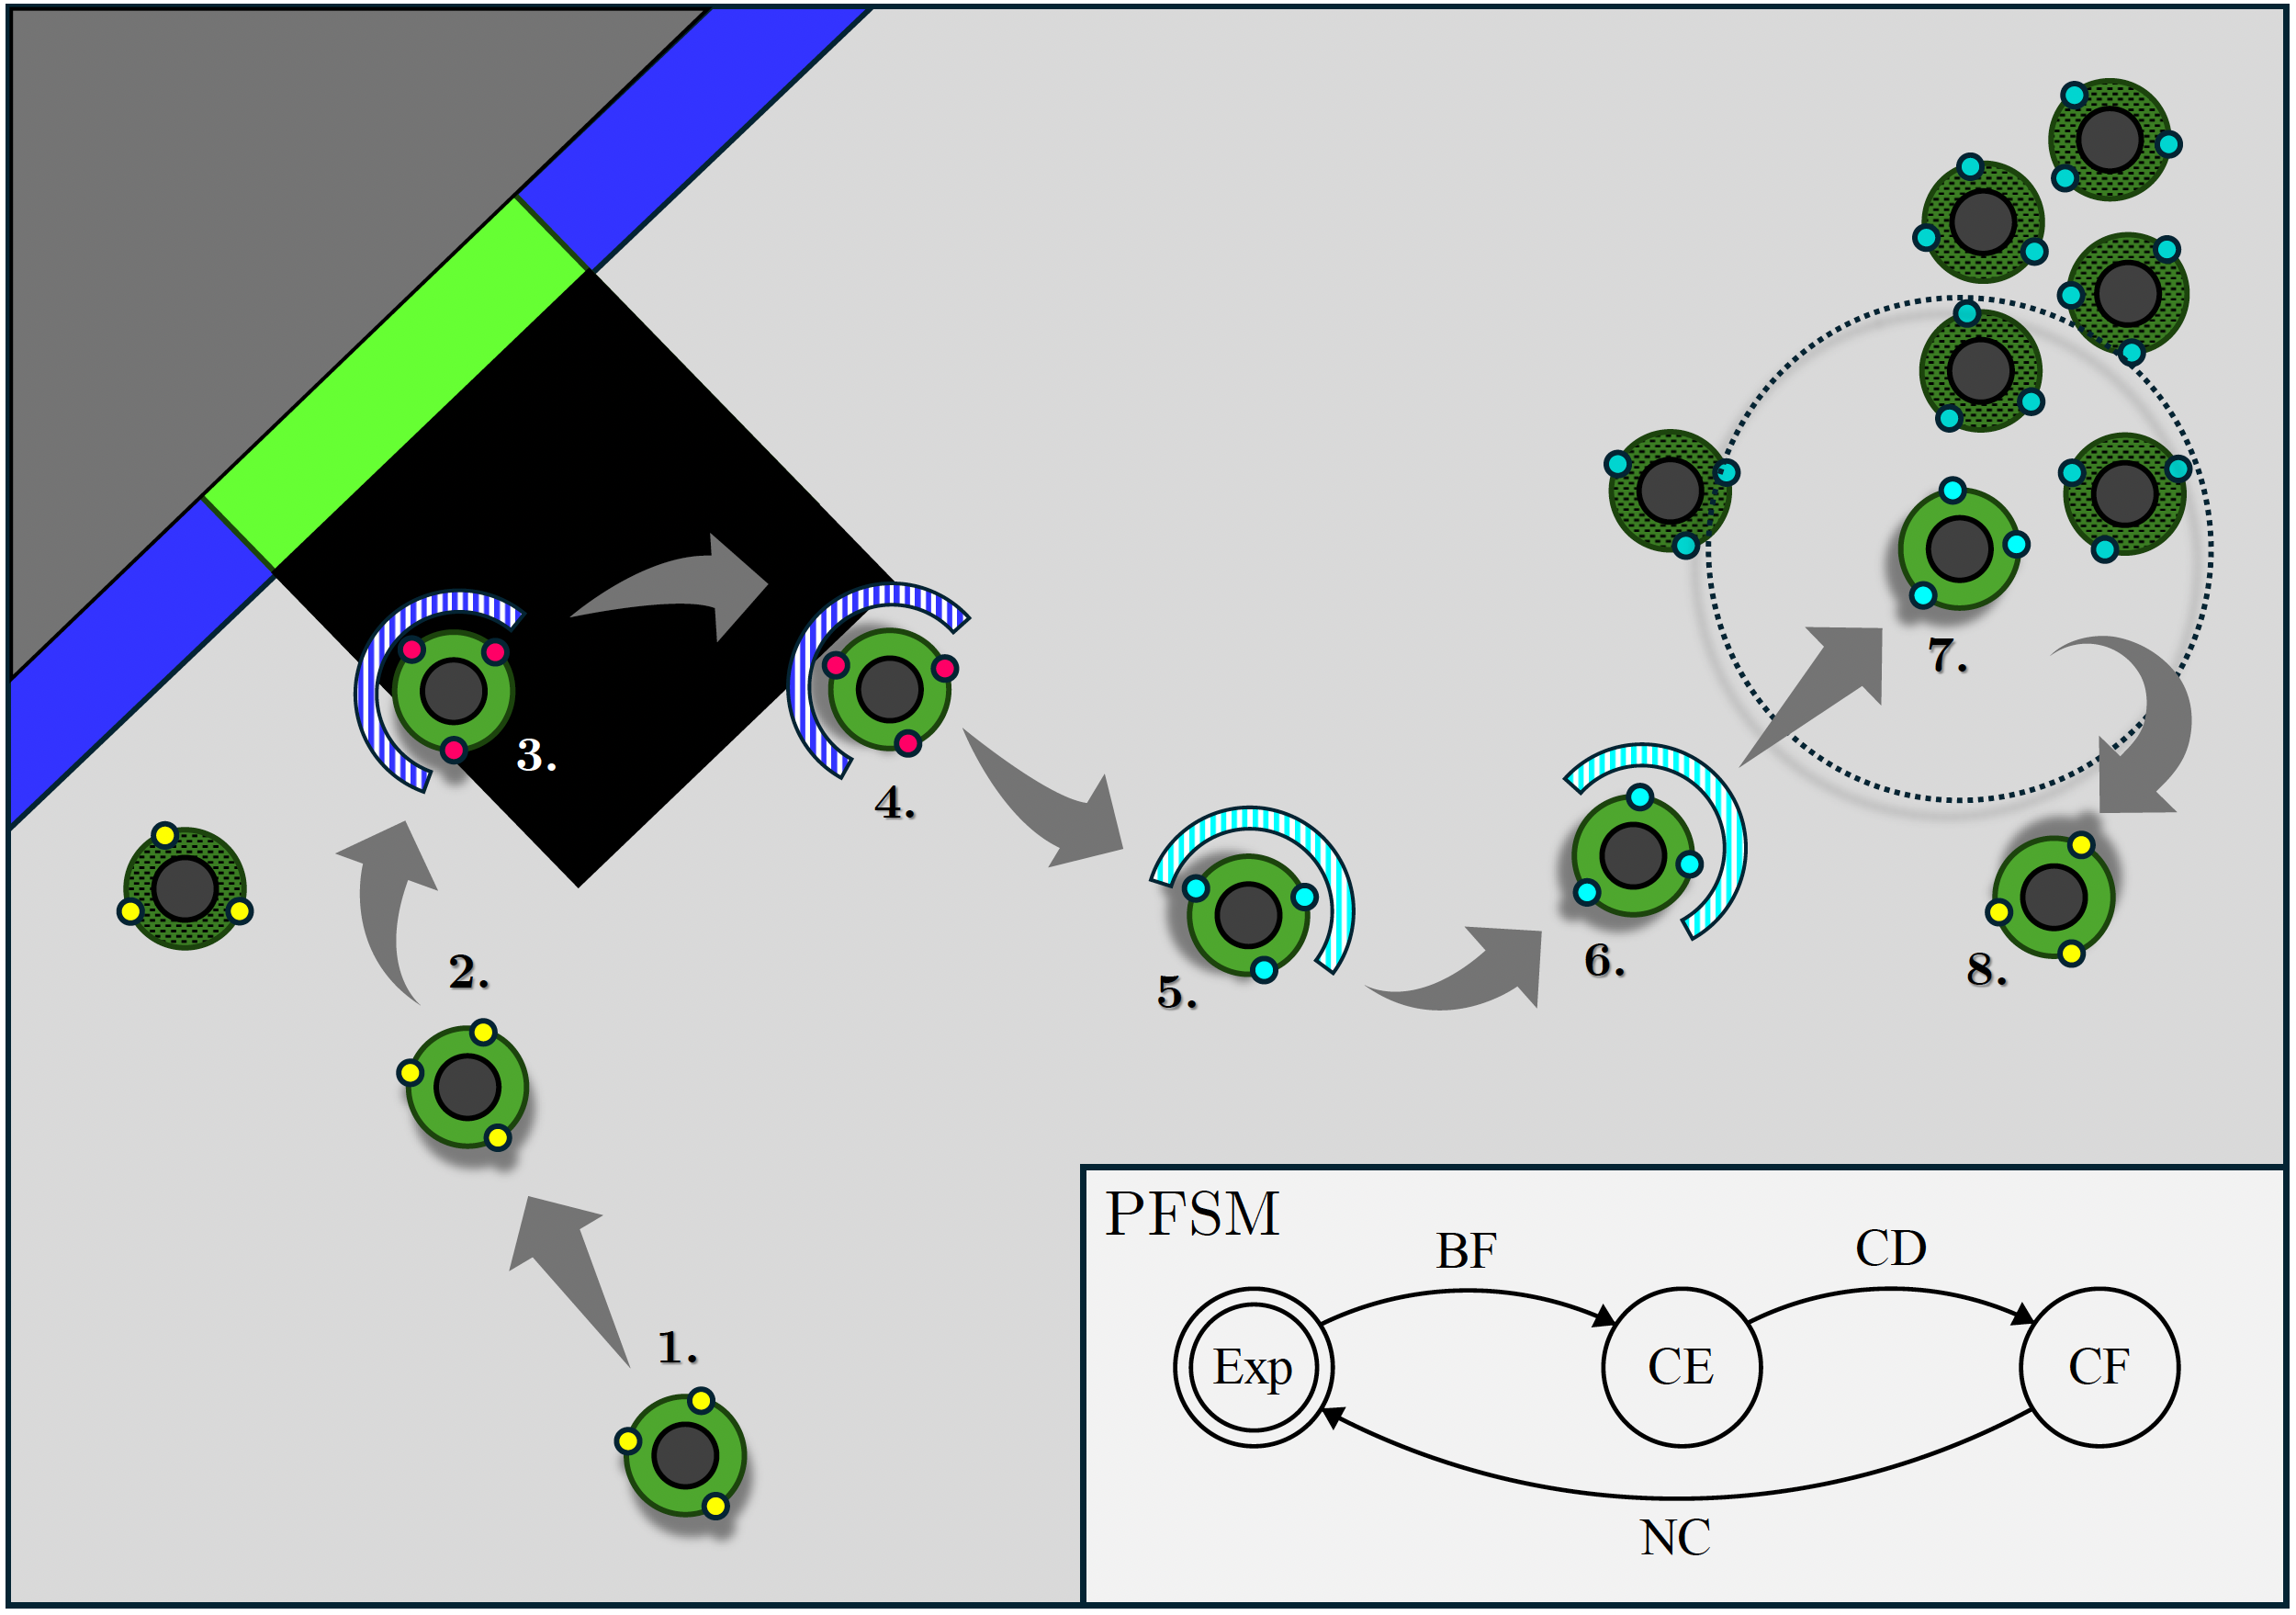 Figure 2. Simplified illustration of TuttiFrutti’s software modules assembled into a probabilistic finite-state machine (PFSM) and the resulting behavior on an e-puck, by Garzón Ramos et al.
Read explanation
- The finite-state machine starts with the behavior Explore (Exp), which in this case sets the e-puck’s LEDs to display yellow while the robot moves randomly in the arena.
- The e-puck detects a robot on its left and turns right to avoid a collision.
- When the e-puck detects a region with a black floor, the transition Black Floor (BF) is activated, and the e-puck switches to the behavior Color Elude (CE).
- The e-puck executes Color Elude (CE), driving the robot away from the blue walls and changing its LEDs to display magenta.
- The e-puck detects that other robots are displaying cyan with their LEDs, activating the transition Color Detection (CD) and switching to the behavior Color Follow (CF).
- The e-puck executes Color Follow (CF), moving toward other robots displaying cyan and changing its own LEDs to cyan as well.
- The e-puck detects two neighboring robots within its perception range, activating the transition Neighbor Count (NC) and switching back to Explore (Exp).
- The finite-state machine continues to operate until the mission ends.
In TuttiFrutti, the design process is conducted by an optimization algorithm that searches the space of possible control software for good-performing instances. This means that an optimization algorithm selects a possible combination of behavior modules, tunes its parameters, evaluates the performance of the swarm in simulation, and then iterates the process until a training budget is exahusted.
Conversely, in this practical session, the students will take on the role of optimization agents, combining and tuning TuttiFrutti’s software modules to create good-performing control software for the robots. The goal of this practical session is therefore to demonstrate how parametric software modules can be combined in different ways to obtain a variety of collective behaviors with a robot swarm.
To perform the exercise, students are provided with a visualization tool [4] (i) to produce and manipulate finite-state machines, (ii) to visualize simulations [5] of the resulting collective behavior, and (iii) to compute the performance of the swarm in each mission.
Running the software
After installing the required software, open a new terminal (in the container, VM, or your PC). Enter the work directory and source the relevant environmental variables:
cd ~/sigsoft-swarms
source argos3-env.sh
Start an experiment by running the following script. Replace ID by the number of the mission you want to test, between 1 and 21—see Experimental scenarios.
bash start_experiment.sh ID
Then, open the following URL in a browser,
http://localhost:8088
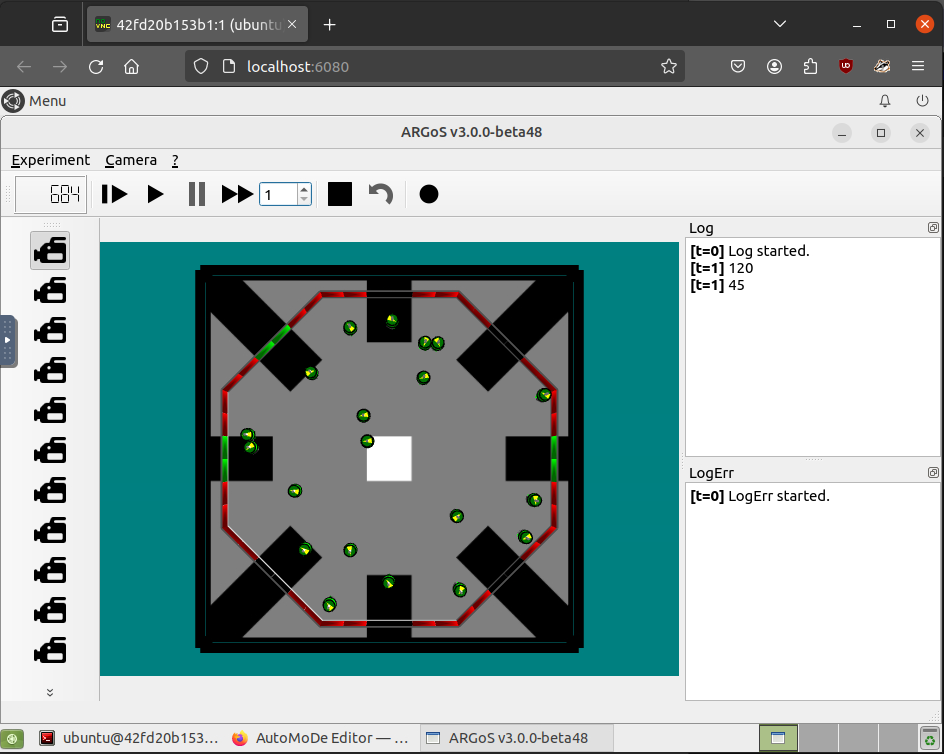
This will spawn an interface that will allow you to create finite state-machines to program the robots and run simulations in ARGoS3—see the figure below.
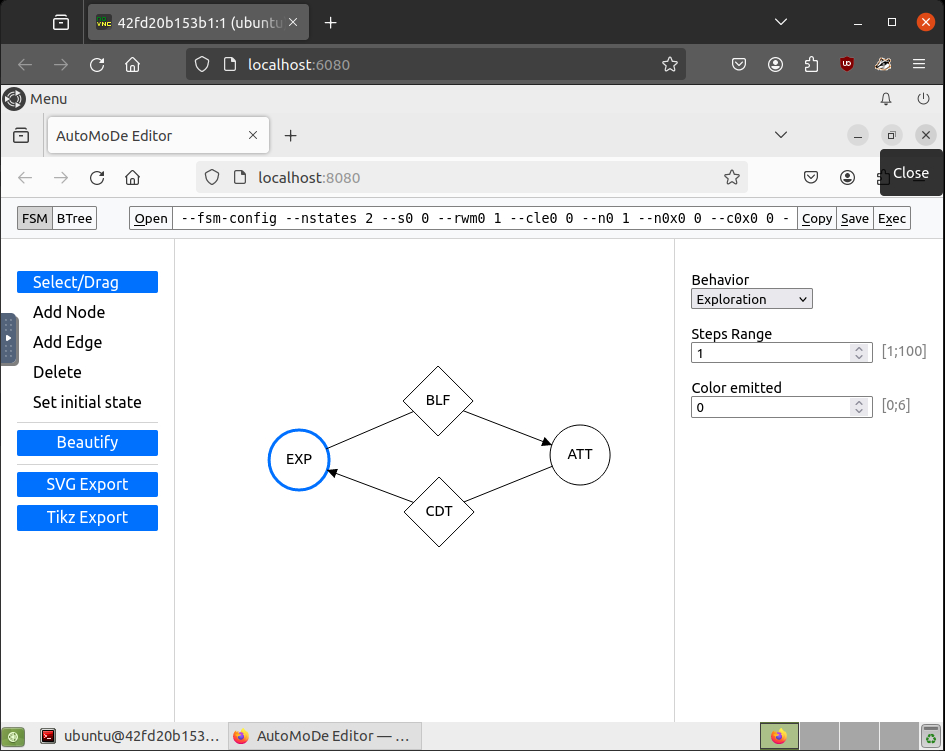
The interface allows you to add, remove, and reorganize nodes and edges in your finite state-machine. By clicking in a software module (either a node or an edge) you will have access to the parameters that can be modified in each case. For example, you can select the type of node and its functional parameters. When you are satisfied with your design, click on the Exec button to spawn the ARGoS3 simulator and play the simulation to observe the behavior of the robots.
Designing modular control software for robot swarms
You can design control software in the form of a probabilistic finite-state machine. In this architecture, states (nodes) represent low-level behaviors that the robots execute, and transition conditions (edges) represent events that trigger the change from one behavior to another. Each low-level behavior and transition condition is a parametric software module. You can design finite-state machines that have up to 4 states and up to 4 outgoing transitions from each state. The set of software modules that are available during the experiment is composed of 6 low-level behaviors (nodes) and 7 transition conditions (edges).
Low-level behaviors
The table below summarizes the set of TuttiFrutti’s low-level behaviors.
| Low-level behavior * | Parameters | Description |
|---|---|---|
Exploration | ${\tau,\gamma}$ | movement by random walk |
Stop | ${\gamma}$ | standstill state |
Attraction | ${\alpha,\gamma}$ | physics-based attraction to neighboring robots |
Repulsion | ${\alpha,\gamma}$ | physics-based repulsion from neighboring robots |
Follow | ${\delta,\gamma}$ | steady movement towards robots/objects of color $\delta$ |
Elude | ${\delta,\gamma}$ | steady movement away from robots/objects of color $\delta$ |
* All low-level behaviors display a color $\gamma\in\{\varnothing,C,M,Y\}$ alongside the action described.
Parameters:
- The parameter
Steps range($\tau\in{1, 100}$) determines the maximum number of time steps that a robot rotates when it faces an obstacle. - The parameter
Attraction($\alpha\in{1, 5}$) is the attraction factor to neighboring robots. - The parameter
Repulsion($\alpha\in{1, 5}$) is the repulsion factor from neighboring robots. - The parameter
Color perceived($\delta\in{1, 6}$) determines the color to which a robot reacts in a given state:- 1 → Red
- 2 → Green
- 3 → Blue
- 4 → Yellow
- 5 → Magenta
- 6 → Cyan
- All low-level behaviors enable the robot for displaying a color with its LEDs. The parameter
Color emitted($\gamma\in{0,6}$) determines the color that the robot displays:- 0 → No color
- 1 → Red
- 2 → Green
- 3 → Blue
- 4 → Yellow
- 5 → Magenta
- 6 → Cyan
Transition conditions
The table below summarizes the set of TuttiFrutti’s transition conditions.
| Transition condition | Parameters | Description |
|---|---|---|
Black-floor | ${\beta}$ | black floor beneath the robot |
Gray-floor | ${\beta}$ | gray floor beneath the robot |
White-floor | ${\beta}$ | white floor beneath the robot |
Many-neighbors | ${\xi,\eta}$ | number of neighboring robots greater than $\xi$ |
Few-neighbors | ${\xi,\eta}$ | number of neighboring robots less than $\xi$ |
Fixed-probability | ${\beta}$ | transition with a fixed probability |
Color-perceived | ${\delta,\beta}$ | robots/objects of color $\delta$ perceived |
Parameters:
- In all transitions, the parameter
Probability($\beta\in[0, 1]$) determines the probability of executing a transition when the given condition is fulfilled. - The parameter $\eta\in{1, 10}$ determines the sensitivity at which the transition triggers when the robot is in the presence of $\xi\in{0, 20}$ neighboring robots.
- The parameter
Color perceived($\delta\in{1, 6}$) determines the color that triggers the transition:- 1 → Red
- 2 → Green
- 3 → Blue
- 4 → Yellow
- 5 → Magenta
- 6 → Cyan
Experimental scenarios
You will experiment with a swarm of twenty e-puck robots that must perform single-criterion missions, or multi-criteria missions composed of two sequential parts [6]. We create missions by combining a set of 6 sub-missions. For each sub-mission, the performance of the swarm is evaluated by an independent objective function: the design criteria.
The robots operate in an octagonal arena of $2.75\,\text{m}^{2}$ surrounded by RGB blocks—see the figure below. The robots are randomly positioned at the beginning of each experimental run. The RGB blocks are arranged in walls and each of them can possibly display a different color. The floor of the arena is gray with nine square patches, each measuring 25 cm on each side. One of the patches is white, and the other eight are black. In every mission, RGB blocks adjacent to black patches initially turn green, and afterward, they will randomly switch off with uniform probability. The remaining RGB blocks turn red or blue to inform the robots about the sub-mission to be executed.
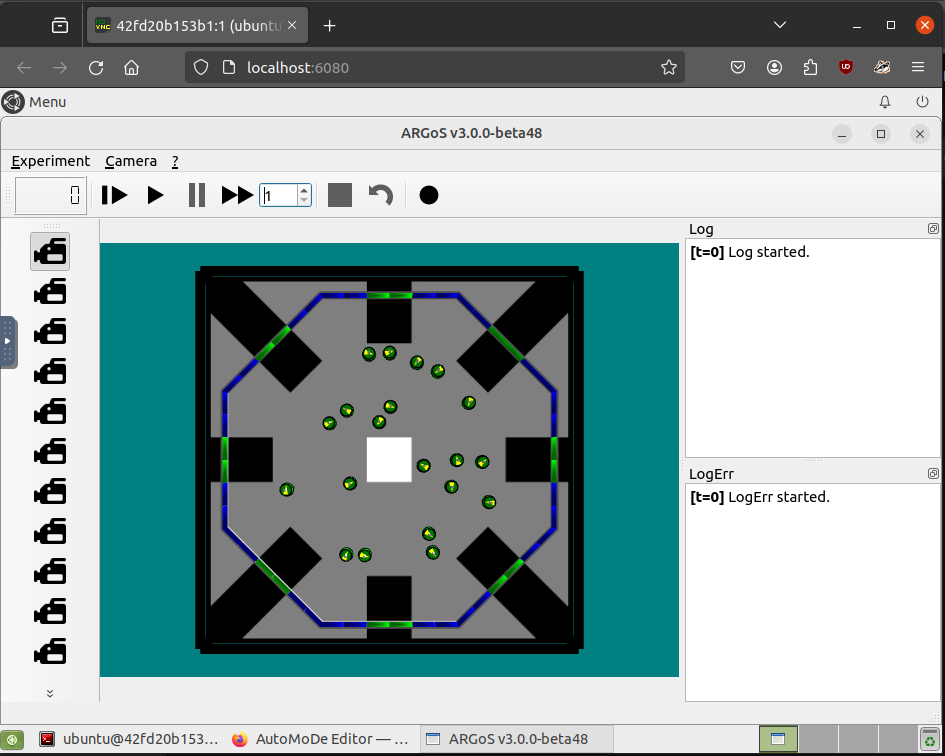
The experimental arena. The pictures show examples of the two possible states of the arena. At the top, the RGB blocks of the walls display blue and all RGB blocks adjacent to a black patch are switched on, displaying green. At the bottom, the RGB blocks of the walls display red and some RGB blocks adjacent to a black patch have switched off, displaying no color. The robots are randomly positioned.
Sub-missions
We consider a set of six sub-missions ($\text{S}${${1,\cdots,6}$}). Each sub-mission is specified by a description of a task to be executed and a corresponding objective function.
Sub-mission 1 ($\mathbf{S1}$)
The robots must occupy the black patches whose adjacent RGB blocks display green. The swarm is given 1 point for every 100 cumulative timesteps that the robots spend on each suitable patch. For example, a single robot in a patch will be given one point after 100 timesteps, but 10 robots in a patch will be given 1 point after 10 timesteps.
The score of the swarm is the number of points it obtains in the allotted time:
$$f_{\text{S}1}=\sum_{t=1}^{T^{\prime}}\sum_{i=1}^{H}I_{i}(t),$$
which must be maximized. $H$ is the number of patches and $T^{\prime}$ the time available to the robots to perform the sub-mission. The indicator $I_{i}(t)$ is defined as:
$$I_{i}(t)=\begin{cases} 1, & \text{if at time $t$ the robots accumulate 100 timesteps in the patch $i$;} \\0, & \text{otherwise}.\end{cases}$$
Sub-mission $\text{S}1$ is inspired by aggregation missions in which the robots must gather at an indicated place [7],[8].
Sub-mission 2 ($\mathbf{S2}$)
The robots must iteratively travel from any black patch to the white one. The swarm is given 1 point every time a robot completes a trip.
The score of the swarm is the number of points it obtains in the allotted time:
$$f_{\text{S}2}=I_{T^{\prime}},$$
which must be maximized. $I_{T^{\prime}}$ is the number of trips executed in the time $T^{\prime}$ available to the robots to perform the sub-mission.
Sub-mission $\text{S}2$ is inspired by foraging missions in which the robots must travel between two locations: a food source and a nest [3],[7].
Sub-mission 3 ($\mathbf{S3}$)
The robots must occupy the black patches adjacent to RGB blocks that are switched off. The swarm is given one point if at least two robots spend 50 timesteps in the corresponding black patch. The count of timesteps starts as soon as the two robots step into the patch, and it will continue as long as they both remain on it. The count is not affected if more than two robots occupy the patch.
The score of the swarm is the number of points it obtains in the allotted time:
$$f_{\text{S}3}=\sum_{t=1}^{T^{\prime}}\sum_{i=1}^{H}I_{i}(t),$$
which must be maximized. $H$ represents the number of patches and $T^{\prime}$ the time available to the robots to perform the sub-mission. The indicator $I_{i}(t)$ is defined as:
$$I_{i}(t)=\begin{cases} 1, & \text{if at time $t$ two robots accumulate 50 timesteps in the patch $i$;} \\0, & \text{otherwise}.\end{cases}$$
Sub-mission $\text{S}3$ is inspired by strictly cooperative missions in which the robots must jointly perform a single task [9],[10].
Sub-mission 4 ($\mathbf{S4}$)
The robots must iteratively enter and leave the white patch. The swarm is awarded 1 point every time a robot performs these two actions.
The score of the swarm is the number of points it obtains in the allotted time:
$$f_{\text{S}4}=I_{T^{\prime}},$$
which must be maximized. $I_{T^{\prime}}$ is the number of times a robot entered and left the white patch in the time $T^{\prime}$ that is available to the robots to perform the sub-mission.
Also sub-mission $\text{S}4$ is inspired by foraging missions, as sub-mission $\text{S}2$, but here, the robots start and end at a single location.
Sub-mission 5 ($\mathbf{S5}$)
The robots must disperse and cover the arena. We consider the coverage to be the most effective when the minimum distance between any two pair of robots is maximized.
The score of the swarm is the cumulative sum of the minimum inter-robot distance, over time:
$$f_{\text{S}5}=\sum_{t=1}^{T^{\prime}}\min\big(d_{ij}(t)\big),$$
which must be maximized. Here, $d_{ij}$ is the minimum distance between any pair of robots ($i,j$) at time $t$, and $T^{\prime}$ is the time available to the robots to perform the sub-mission.
Sub-mission $\text{S}5$ is inspired by dispersion and coverage missions in which the robots must maintain a fixed inter-robot distance to achieve a specific spatial distribution [8],[11].
Sub-mission 6 ($\mathbf{S6}$)
The robots must remain within a 25 cm distance from the walls of the arena, without entering the black patches.
The score of the swarm is the aggregate time that the robots spend in the suitable areas:
$$f_{\text{S}6}=\sum_{t=1}^{T^{\prime}}\sum_{i=1}^{N}I_{i}(t),$$
which must be maximized. $N$ is the number of robots and $T^{\prime}$ is the time available to the robots to perform the sub-mission. The indicator $I_{i}(t)$ is defined as:
$$I_{i}(t)=\begin{cases} 1, & \text{if the robot $i$ is in gray floor and in a 25 cm distance from a wall at time $t$;} \\0, & \text{otherwise}.\end{cases}$$
Sub-mission $\text{S}6$ is inspired by missions in which the robots must display a specific spatial distribution, like sub-mission $\text{S}5$ [8],[11]. However, the robots here must maintain a specific distance from an element in their environment, irrespective of the distance to their peers.
Single-criteria missions
We define the set $\text{M}_{s}$ of single-criteria missions ($m_{\text{S}p.\text{S}p}$) by evaluating a single sub-mission in both parts of the mission, where $p=q$. This results in 6 missions—see the table below.
The time $T$ available to the robots to execute a mission is 120 s. Accordingly, the swarm’s performance in a mission is assessed for the whole time regarding a single performance metric. A single score is returned after each experimental run. We expect the swarm to be able to perform a mission $m_{\text{S}p.\text{S}q}$ regardless of the order of $\text{S}p$ and $\text{S}q$.
| ID | Mission | Sub-mission $\text{S}p$ | Sub-mission $\text{S}q$ | |
|---|---|---|---|---|
| 1 | $m_{\text{S}1.\text{S}1}$ | $\text{S}1$ | $\rightleftarrows$ | $\text{S}1$ |
| 2 | $m_{\text{S}2.\text{S}2}$ | $\text{S}2$ | $\rightleftarrows$ | $\text{S}2$ |
| 3 | $m_{\text{S}3.\text{S}3}$ | $\text{S}3$ | $\rightleftarrows$ | $\text{S}3$ |
| 4 | $m_{\text{S}4.\text{S}4}$ | $\text{S}4$ | $\rightleftarrows$ | $\text{S}4$ |
| 5 | $m_{\text{S}5.\text{S}5}$ | $\text{S}5$ | $\rightleftarrows$ | $\text{S}5$ |
| 6 | $m_{\text{S}6.\text{S}6}$ | $\text{S}6$ | $\rightleftarrows$ | $\text{S}6$ |
Set of single-criteria missions ($\text{M}_s$). The missions are execution of each of the six sub-missions ($\text{S}_{\{1,\cdots,6\}}$). The colors blue and red characterize the sub-missions $\text{S}p$ () and $\text{S}q$ (). In a mission ($m_{\text{S}p.\text{S}q}$), the sub-missions $\text{S}p$ and $\text{S}q$ represent the same sub-mission ($p=q$), but the order of the sequence and colors ($\text{S}p$ $\rightleftarrows$ $\text{S}q$) is randomly defined in every experimental run. $\text{S}p$ and $\text{S}q$ are executed during an equivalent period of time. The execution of a mission $m_{\text{S}p.\text{S}q}$ returns a single score for the swarm with respect to the corresponding sub-mission, regardless of the order of the sequence.
Multi-criteria missions
We define the set $\text{M}$ of multi-criteria missions ($m_{\text{S}p.\text{S}q}$) by pairing sub-missions ($\text{S}p$, $\text{S}q$) in fifteen combinations—see the table below. Unlike the single-criteria missions, in this case $p\neq q$.
In all cases, the robots must execute the two sub-missions, one after the other. The time $T$ available to the robots to execute a mission is 120 s. The time $T^{\prime}$ available to execute each sub-mission is 60 s. Accordingly, the swarm’s performance in a mission is assessed for the initial 60 s with regard to one sub-mission and for the remaining 60 s with regard to the other. The two scores are returned after each experimental run. We expect the swarm to be able to perform a mission $m_{\text{S}p.\text{S}q}$ regardless of the order of $\text{S}p$ and $\text{S}q$.
| ID | Mission | Sub-mission $\text{S}p$ | Sub-mission $\text{S}q$ | |
|---|---|---|---|---|
| 7 | $m_{\text{S}1.\text{S}2}$ | $\text{S}1$ | $\rightleftarrows$ | $\text{S}2$ |
| 8 | $m_{\text{S}1.\text{S}3}$ | $\text{S}1$ | $\rightleftarrows$ | $\text{S}3$ |
| 9 | $m_{\text{S}1.\text{S}4}$ | $\text{S}1$ | $\rightleftarrows$ | $\text{S}4$ |
| 10 | $m_{\text{S}1.\text{S}5}$ | $\text{S}1$ | $\rightleftarrows$ | $\text{S}5$ |
| 11 | $m_{\text{S}1.\text{S}6}$ | $\text{S}1$ | $\rightleftarrows$ | $\text{S}6$ |
| 12 | $m_{\text{S}2.\text{S}3}$ | $\text{S}2$ | $\rightleftarrows$ | $\text{S}3$ |
| 13 | $m_{\text{S}2.\text{S}4}$ | $\text{S}2$ | $\rightleftarrows$ | $\text{S}4$ |
| 14 | $m_{\text{S}2.\text{S}5}$ | $\text{S}2$ | $\rightleftarrows$ | $\text{S}5$ |
| 15 | $m_{\text{S}2.\text{S}6}$ | $\text{S}2$ | $\rightleftarrows$ | $\text{S}6$ |
| 16 | $m_{\text{S}3.\text{S}4}$ | $\text{S}3$ | $\rightleftarrows$ | $\text{S}4$ |
| 17 | $m_{\text{S}3.\text{S}5}$ | $\text{S}3$ | $\rightleftarrows$ | $\text{S}5$ |
| 18 | $m_{\text{S}3.\text{S}6}$ | $\text{S}3$ | $\rightleftarrows$ | $\text{S}6$ |
| 19 | $m_{\text{S}4.\text{S}5}$ | $\text{S}4$ | $\rightleftarrows$ | $\text{S}5$ |
| 20 | $m_{\text{S}4.\text{S}6}$ | $\text{S}4$ | $\rightleftarrows$ | $\text{S}6$ |
| 21 | $m_{\text{S}5.\text{S}6}$ | $\text{S}5$ | $\rightleftarrows$ | $\text{S}6$ |
Set of multi-criteria missions ($\text{M}$). The missions are paired combinations ($m_{\text{S}p.\text{S}q}$) of the six sub-missions ($\text{S}_{\{1,\cdots,6\}}$). In each combination, the colors blue and red characterize the sub-missions $\text{S}p$ () and $\text{S}q$ (). In a mission ($m_{\text{S}p.\text{S}q}$), the sub-missions $\text{S}p$ and $\text{S}q$ must be executed in sequence, but the order of the sequence ($\text{S}p$ $\rightleftarrows$ $\text{S}q$) is randomly defined in every experimental run. $\text{S}p$ and $\text{S}q$ are executed during an equivalent period of time. The execution of a mission $m_{\text{S}p.\text{S}q}$ returns the score of the swarm with respect to $\text{S}p$ and $\text{S}q$, regardless of the order of the sequence.
Proposed solutions
Proposed solutions for the missions in this session will be available soon.
To be considered
While conducting the experiments, consider the following questions and reflect on how they influence the design process you use to achieve a satisfactory solution for a mission.
- How do you know whether the swarm is already operating in a satisfactory manner? How do you know if the swarm has a sufficiently good performance?
- Does the performance of the swarm vary from one run to the other? If so, what can cause such variance?
- Can you think of a strategy to decide the effort you devote to address each mission?
- What factors influence your design process in the multi-criteria mission? Are there reasons to favour one criteria over the other?
References
[1] M. Dorigo, M. Birattari, and M. Brambilla, "Swarm robotics," Scholarpedia, vol. 9, no. 1, p. 1463, 2014. [Link]
[2] M. Brambilla, E. Ferrante, M. Birattari, and M. Dorigo, "Swarm robotics: a review from the swarm engineering perspective," Swarm Intelligence, vol. 7, no. 1, pp. 1–41, 2013. [DOI]
[3] D. Garzón Ramos and M. Birattari, "Automatic design of collective behaviors for robots that can display and perceive colors," Applied Sciences, vol. 10, no. 13, p. 4654, 2020. [DOI]
[4] J. Kuckling, K. Hasselmann, V. van Pelt, C. Kiere, and M. Birattari, "AutoMoDe Editor: a visualization tool for AutoMoDe," IRIDIA, Université libre de Bruxelles, Tech. Rep. TR/IRIDIA/2021-009, 2021. [Link]
[5] C. Pinciroli et al., "ARGoS: a modular, parallel, multi-engine simulator for multi-robot systems," Swarm Intelligence, vol. 6, no. 4, pp. 271–295, 2012. [DOI]
[6] D. Garzón Ramos, F. Pagnozzi, T. Stützle, and M. Birattari, "Automatic design of robot swarms under concurrent design criteria: a study based on Iterated F-Race," Advanced Intelligent Systems, vol. 7, no. 1, p. 2400332, 2024. [DOI]
[7] G. Francesca, M. Brambilla, A. Brutschy, V. Trianni, and M. Birattari, "AutoMoDe: a novel approach to the automatic design of control software for robot swarms," Swarm Intelligence, vol. 8, no. 2, pp. 89–112, 2014. [DOI]
[8] G. Francesca et al., "AutoMoDe-Chocolate: automatic design of control software for robot swarms," Swarm Intelligence, vol. 9, no. 2-3, pp. 125–152, 2015. [DOI]
[9] A. J. Ijspeert, A. Martinoli, A. Billard, and L. M. Gambardella, "Collaboration through the exploitation of local interactions in autonomous collective robotics: the stick pulling experiment," Autonomous Robots, vol. 11, no. 2, pp. 149–171, 2001. [DOI]
[10] V. Trianni and M. López-Ibáñez, "Advantages of task-specific multi-objective optimisation in evolutionary robotics," PLOS ONE, vol. 10, no. 8, p. e0136406, 2015. [DOI]
[11] F. J. Mendiburu, D. Garzón Ramos, M. R. A. Morais, A. M. N. Lima, and M. Birattari, "AutoMoDe-Mate: automatic off-line design of spatially-organizing behaviors for robot swarms," Swarm and Evolutionary Computation, vol. 74, p. 101118, 2022. [DOI]
Contact
Like robot swarms, the swarm robotics community thrives through collaboration. If you would like to contribute to this page, please do not hesitate to get in touch.
David Garzón Ramos
University College Dublin
[email protected]
Feedback, erratas, bug reports, corrections, clarifications, extensions, and new content are all welcomed!
Credits
This course page was created by David Garzón Ramos, LIMAR, University College Dublin (UCD), and funded by IEEE RAS and a UCD Ad Astra Fellowship. The preparation of the material was assisted by Juan B. Medina, PhD student at University College Dublin.
Section 10.1 Swarm Robotics is based on ideas and reserch developed by David Garzón Ramos in collaboration with researchers at IRIDIA, the Artificial Intelligence Laboratory of Université libre de Bruxelles (ULB), and the Bristol Robotics Laboratory, University of Bristol.
Section 10.2 Practice on Collective Behaviors builds on the ideas an excercises developed by Marco Dorigo and Mauro Birattari in the Swarm Intelligence course of IRIDIA at ULB. The original implementation of this excercises is credited to Carlo Pinciroli, Head of NEST Lab, Worcester Polytechnic Institute.
Section 10.3 Practice on Modular Design builds on the ideas an excercises developed by David Garzón Ramos and Mauro Birattari for AutoMoDe TuttiFrutti and Mandarina, with an interface designed by Jonas Kuckling, University of Konstanz.